
Use MTA for tactical, consented digital optimization. Use MMM for strategic cross-channel budget decisions. Run a privacy-first hybrid when you need both. That’s the whole answer. Everything below is the implementation detail.
Quick use-case guide:
- DTC e-commerce with clean first-party data: Start with MTA for campaign-level creative and placement decisions; layer MMM quarterly to validate budget splits across channels.
- Retail with significant offline spend (TV, OOH, in-store): MMM is your primary tool. MTA can’t see offline, so it will systematically undervalue upper-funnel channels.
- B2B with sales cycles longer than 60 days: MTA breaks down because the conversion window exceeds most attribution lookback periods. MMM with CRM pipeline data is more reliable.
- High-consent digital-first teams (strong first-party data, solid consent rates): A hybrid stack is viable right now. Run MTA near-real-time for campaign signals; run MMM monthly for budget governance.
- Small advertisers with limited historical data: Neither method works well below roughly 12–18 months of consistent spend data. Start with platform-native attribution and incrementality tests on your highest-spend channels.
Before you go further, check three things:
- Do you have at least 18 months of weekly spend and outcome data across channels? (MMM minimum)
- What’s your consent capture rate? Below 60–70%, MTA signal quality degrades fast.
- How many channels are you running? Three or fewer digital channels with no offline spend is an MTA-first situation.
Key Takeaways
A privacy-first hybrid stack combining MTA for tactical digital signals, MMM for cross-channel budget governance, and periodic lift tests for causal validation is the most durable measurement architecture available to high-spend advertisers today.
| Point | Details |
|---|---|
| MTA vs MMM primary split | Use MTA for campaign-level digital optimization; use MMM for strategic cross-channel budget decisions. |
| Privacy resilience gap | MTA signal quality degrades 30–50% as identifiers drop; MMM requires no user identifiers and is structurally more resilient. |
| Incrementality is not attribution | Many conversions credited by attribution models are not incremental; lift tests are required to measure true causal impact. |
| Open-source tools available | Google’s Meridian and Meta’s Robyn are viable starting points for MMM; both require data engineering resources and clean historical pipelines. |
| North Country Consulting | Offers a free measurement audit for advertisers spending $25K+/month, covering attribution configuration, consent infrastructure, and hybrid stack readiness. |
Table of Contents
- What is MMM vs MTA, and how does each method actually work?
- How Multi-Touch Attribution (MTA) works
- How Marketing Mix Modeling (MMM) works
- How do MMM and MTA actually differ from each other?
- Pros and cons of MTA and MMM
- When should you use MTA, MMM, or both?
- How to design a privacy-first hybrid MTA + MMM measurement stack
- Why incrementality is different from attribution, and when to run lift tests
- How privacy changes affect MTA and MMM, and what to do about it
- How North Country Consulting combines MTA and MMM for high-spend clients
- North Country Consulting’s measurement audit for high-spend advertisers
- Sources
What is MMM vs MTA, and how does each method actually work?
Multi-Touch Attribution and Marketing Mix Modeling are both designed to answer the same surface-level question: which marketing activities are driving results? But they answer it at completely different levels of analysis, with different data, and for different decisions. Treating them as interchangeable is one of the most common and expensive mistakes in marketing measurement.
MTA works best for short-term digital optimization when consent and identifiers are stable, while MMM is more privacy-resilient and better for long-term, cross-channel budget decisions. That single distinction should drive which one you build first.
How Multi-Touch Attribution (MTA) works
MTA assigns credit for a conversion across the digital touchpoints a user encountered before converting. The unit of analysis is the individual user journey.
Core inputs MTA requires:
- Browser cookies, device IDs, or hashed email identifiers to track users across sessions
- Platform pixels (Google Ads, Meta, etc.) firing on key events
- CRM joins to connect ad exposure to downstream revenue or pipeline
- Server-side conversion events for cookieless environments
The data flow, step by step:
- Capture: Pixels and server-side tags fire on user interactions (impressions, clicks, form fills, purchases).
- Identity stitching: A customer data platform or identity graph links events from the same user across devices and sessions.
- Sessionization: Events are grouped into journeys with defined lookback windows (typically 7–90 days).
- Model scoring: A credit-assignment model distributes conversion value across touchpoints in the journey.
- Reporting: Campaign managers see per-touch, per-creative, and per-placement performance, usually with 24–72 hour latency.
Model types and what they imply:
- Rule-based models (last click, first click, linear, time decay, position-based) are fast and transparent but bake in assumptions that may not reflect reality. Last-click, for example, systematically over-credits bottom-funnel paid search while ignoring the display or video touch that started the journey.
- Data-driven models (Shapley value, Markov chains, logistic regression) use observed conversion paths to assign credit statistically. They’re more accurate but require substantial conversion volume, typically 3,000+ conversions per month to be statistically stable. Google Ads’ data-driven attribution model uses this approach.
The outputs are tactical: which ad creative drove the most assisted conversions, which placement is over-funded relative to its contribution, which audience segment converts fastest. MTA is built for campaign managers making weekly or daily decisions.
How Marketing Mix Modeling (MMM) works
MMM takes the opposite approach. Instead of tracking individual users, it analyzes aggregated historical data to estimate how much each marketing channel contributed to overall outcomes, after controlling for everything else that affects sales.
What goes into an MMM model:
- Weekly or monthly spend by channel (paid search, paid social, TV, radio, OOH, email, organic)
- Outcome metrics (revenue, units sold, leads, store visits)
- Seasonality and holiday controls
- Pricing and promotional variables
- Distribution or inventory factors
- Macro controls (economic indicators, competitor activity where available)
- Adstock and carryover parameters (how long a channel’s effect persists after spend stops)
The statistical engine is typically a Bayesian regression or a time-series regression that isolates each channel’s marginal contribution to the outcome variable. The model needs at least 12–18 months of weekly data to estimate seasonality reliably; two years is better. Geo-level data (state or DMA) adds granularity and supports geo-based incrementality validation.
What MMM outputs:
- Channel contribution percentages (what share of revenue each channel drove)
- ROI and marginal ROI curves per channel
- Diminishing returns curves (where additional spend stops paying off)
- Scenario simulations for budget reallocation
Where open-source tools fit:
Google’s Meridian is an open-source MMM framework that integrates with BigQuery and uses Bayesian inference, making it a practical starting point for teams with data engineering resources. Meta’s Robyn is another open-source option, built in R, that’s widely used for experimentation before committing to a production MMM stack. Both tools require a data engineer or analyst comfortable with Python or R, clean historical data pipelines, and a defined outcome metric. Neither is a plug-and-play solution.
How do MMM and MTA actually differ from each other?
| Dimension | Multi-Touch Attribution (MTA) | Marketing Mix Modeling (MMM) |
|---|---|---|
| Best for / primary question | Which digital touchpoints contributed to this conversion? | Where should the next dollar go across all channels? |
| Data granularity | User-level (individual journeys) | Aggregate (weekly/monthly totals) |
| Time horizon | Short-term, tactical (days to weeks) | Medium to long-term, strategic (months to years) |
| Channels covered | Digital only (paid search, paid social, display, email) | Digital + offline (TV, radio, OOH, in-store) |
| Privacy resilience | Low: degrades with cookie loss, consent drop, and ID fragmentation | High: uses aggregated spend data, no user identifiers required |
| Typical outputs | Per-campaign, per-creative, per-placement performance | Channel ROI curves, budget scenarios, diminishing returns |
| Complexity / engineering | Moderate: pixel setup, identity graph, CDP or data warehouse | High: historical data pipelines, statistical modeling, calibration |
| Link to incrementality | Attribution ≠ causation; lift tests validate MTA findings | MMM can be calibrated with geo-based lift tests for higher accuracy |
Practical implications by dimension:
- Granularity: MTA tells you that Keyword A outperformed Keyword B last week. MMM tells you that paid search as a category drove 28% of revenue over the past year. You need both to make good decisions.
- Time horizon: MMM requires months of data to produce stable estimates. It’s not a tool for reacting to a campaign that launched Tuesday.
- Channels: If TV or OOH is in your media mix, MTA simply cannot measure it. MMM is the only option for cross-channel budget decisions that include offline.
- Privacy resilience: As third-party cookies continue to erode, MTA signal quality drops. MMM doesn’t care about cookies at all.
- Outputs: MTA outputs feed campaign managers. MMM outputs feed CMOs and CFOs making quarterly budget decisions.
Where results commonly diverge: MTA tends to over-credit bottom-funnel channels (branded paid search, retargeting) because those touchpoints appear last in the conversion path. MMM, which controls for baseline demand, often shows those channels have lower incremental ROI than MTA suggests. When the two models disagree significantly on a channel’s value, that’s a signal to run a lift test, not to trust one model over the other.
Pros and cons of MTA and MMM
MTA strengths and limitations
Pros:
- Near-real-time feedback on campaign performance
- Granular creative and placement insights
- Directly actionable for campaign managers and media buyers
- Integrates with Google Ads, Meta, and most DSPs for automated bidding signals
Cons:
- Depends on user-level identifiers that are increasingly unavailable (Safari ITP, Firefox ETP, iOS privacy changes, GDPR/CCPA consent requirements)
- Cannot measure offline channels or upper-funnel brand effects
- Rule-based models embed assumptions that distort credit assignment
- Data-driven models require high conversion volume to be reliable
- Attribution is not incrementality: many conversions credited by MTA would have happened without the advertising
Common misinterpretation: Last-click attribution in Google Ads routinely inflates branded search’s apparent contribution. A user who saw a YouTube ad, a display ad, and then searched for your brand name will have the entire conversion credited to the brand search click. MTA sees that as a search win. MMM, controlling for organic brand demand, often tells a different story.
MMM strengths and limitations
Pros:
- Privacy-resilient by design: no user identifiers required
- Covers all channels including TV, radio, OOH, and in-store
- Captures long-term brand effects and adstock carryover
- Produces budget scenario simulations that MTA cannot
- Increasingly accessible via open-source tools like Meridian and Robyn
Cons:
- Requires 12–18 months of clean historical data minimum
- Results are aggregate: cannot optimize individual campaigns or creatives
- Sensitive to data quality issues (missing spend data, inconsistent outcome metrics)
- Seasonal businesses need even more data to separate seasonality from channel effects
- Model outputs can be weeks or months behind current market conditions
Common misinterpretation: Brand carryover (adstock) is one of the trickiest parameters to set correctly. If the model overestimates how long a TV campaign’s effect persists, it will attribute revenue to TV that was actually driven by a concurrent paid search push. Getting adstock priors right, especially in Bayesian MMM frameworks like Meridian, requires domain knowledge and calibration against lift tests.
When should you use MTA, MMM, or both?
Practitioners should match the method to the question: MTA for tactical channel-level optimizations, MMM for strategic allocation and cross-channel measurement. Using one to answer the other’s question causes bad decisions.
Use MTA when:
- Your primary channels are digital and you have stable first-party data collection
- You need weekly or daily feedback to optimize bids, creatives, or placements
- Your conversion volume is high enough for data-driven models (3,000+ monthly conversions)
- Your consent capture rate is above 70% and you have a functioning server-side tagging setup
Use MMM when:
- Your media mix includes offline channels (TV, radio, OOH, direct mail)
- You’re making quarterly or annual budget allocation decisions
- You have 18+ months of consistent weekly spend and outcome data
- Privacy changes have degraded your MTA signal quality below a reliable threshold
- You need to model diminishing returns or run budget scenario simulations
Use both (hybrid) when:
- You’re a mid-to-large advertiser with both digital and offline channels
- You want MTA for campaign-level decisions and MMM for portfolio-level budget governance
- You have the engineering bandwidth to maintain two data pipelines and reconcile outputs
- You want to use lift tests to cross-validate both models
Organizational readiness checklist before selecting:
- Do you have a data warehouse (BigQuery, Snowflake, Redshift) with clean, consistent historical data?
- Is your consent management platform capturing and storing consent signals at the event level?
- Do you have at least one analyst or data engineer who can own the modeling pipeline?
- Have you defined a single outcome metric that both models will optimize toward?
For small businesses spending under $25K/month with limited channel diversity, neither MMM nor a full MTA stack is worth the investment yet. Platform-native attribution (Google Ads, Meta) plus periodic geo-based lift tests will give you more signal per dollar spent on measurement infrastructure.
How to design a privacy-first hybrid MTA + MMM measurement stack
A hybrid stack isn’t just running both models in parallel. It requires a shared data architecture, aligned definitions, and a governance process for reconciling outputs.
Step-by-step implementation:
-
Build a consent-first data layer. Every event must carry a consent signal. Use a consent management platform (OneTrust, Cookiebot, or a custom implementation) that passes consent status to your tag manager and data warehouse. Events without consent signals should be excluded from MTA modeling but can still contribute to MMM aggregate totals.
-
Unify your spend schema. Define a single spend taxonomy that maps to both models. Channel names, campaign types, and date granularity must be consistent across platforms. A Google Ads “Performance Max” campaign needs a defined home in both your MTA touchpoint data and your MMM spend input table.
-
Set separate modeling cadences. MTA runs near-real-time or daily. MMM runs weekly or monthly. Never try to run MMM at daily granularity; the model will overfit to noise.
-
Normalize spend and outcome data. Deduplicate conversions across platforms before feeding either model. Platform-reported conversions (Google Ads + Meta + TikTok) will sum to more than your actual revenue because each platform claims credit for the same conversion.
-
Choose your tools. For MMM, evaluate Google’s Meridian (Python, Bayesian, BigQuery-native) or Meta’s Robyn (R, open-source, good for experimentation). For MTA, assess whether a platform-native data-driven model is sufficient or whether you need a third-party identity graph. For analytics event tracking, Mixpanel and Amplitude both offer event-level pipelines that can feed MTA models.
-
Cross-validate outputs quarterly. When MTA and MMM disagree on a channel’s contribution by more than 20–30%, investigate before acting. Common causes: adstock miscalibration in MMM, identity fragmentation in MTA, or a channel that’s genuinely performing differently at the user level vs. the aggregate level.
-
Schedule incrementality tests. Plan at least two geo-based or audience-based lift tests per quarter on your highest-spend or most contested channels. Use test results to calibrate MMM priors and validate MTA credit assignments.
Engineer checklist:
- Data contracts defined for every spend and outcome source
- Schema versioning and QA checks on weekly MMM input tables
- Consent signal propagation tested end-to-end
- Deduplication logic documented and audited quarterly
Marketer checklist:
- KPIs defined and agreed upon before modeling begins
- Governance process for acting on MMM budget recommendations
- Experiment calendar aligned with media planning cycle
- Clear owner for each model’s outputs and decisions
Pro Tip: Don’t try to run incrementality tests on every campaign simultaneously. Prioritize tests on channels where MTA and MMM disagree most, where you’re considering a significant budget increase or cut, or where you’re launching into a new audience or channel. Those are the decisions where a causal estimate is worth the cost and delay of a proper lift test.
Why incrementality is different from attribution, and when to run lift tests
Attribution and incrementality are not the same thing, and conflating them is one of the most expensive mistakes in marketing analytics.
Attribution answers which touchpoints receive credit while incrementality answers how many additional conversions marketing caused. Both are complementary for robust measurement, but they answer fundamentally different questions.
Attribution observes which touchpoints appeared in a conversion path and distributes credit among them. It cannot tell you whether removing any of those touchpoints would have changed the outcome. A user who was going to buy anyway, who happened to click a retargeting ad on the way to checkout, will generate an attributed conversion for that retargeting campaign. The campaign gets credit. The conversion was not incremental.
Avinash Kaushik’s point is direct: a large share of conversions credited by attribution models would have happened without the advertising. If you’re using attributed conversions as your primary measure of marketing effectiveness, you’re likely overstating the value of your bottom-funnel retargeting and branded search campaigns.
Incrementality testing works like this: Split your audience or geography into a test group (exposed to the ad) and a control group (held out). Measure the difference in conversion rate between the two groups. That difference is the incremental lift. No path analysis, no credit assignment, just a causal estimate.
When to run a lift test:
- Before a significant budget reallocation (moving 20%+ of spend from one channel to another)
- When launching a new channel or audience segment
- When defending a channel’s budget to leadership and attribution data alone won’t be convincing
- When MTA and MMM disagree significantly on a channel’s value
- Annually on your highest-spend channels as a baseline calibration
Incrementality remains the most reliable way to prove causal impact for a channel, though tests require careful design and take time. A geo-based holdout test on Google Ads, for example, typically needs 2–4 weeks to reach statistical significance, depending on your conversion volume and the size of the effect you’re trying to detect.
Pro Tip: For incrementality testing in PPC, Google Ads’ Campaign Experiments tool lets you run A/B tests at the campaign level with statistical significance reporting built in. It’s not a full geo holdout, but it’s a practical starting point for teams without a dedicated experimentation infrastructure.
How privacy changes affect MTA and MMM, and what to do about it
The measurement environment has shifted materially. Safari and Firefox block third-party cookies by default. iOS 14.5 and later require explicit opt-in for cross-app tracking. GDPR and CCPA enforcement has raised the cost of non-compliant data collection. The practical result: MTA signal quality is degrading for most advertisers, and the trajectory is not reversing.
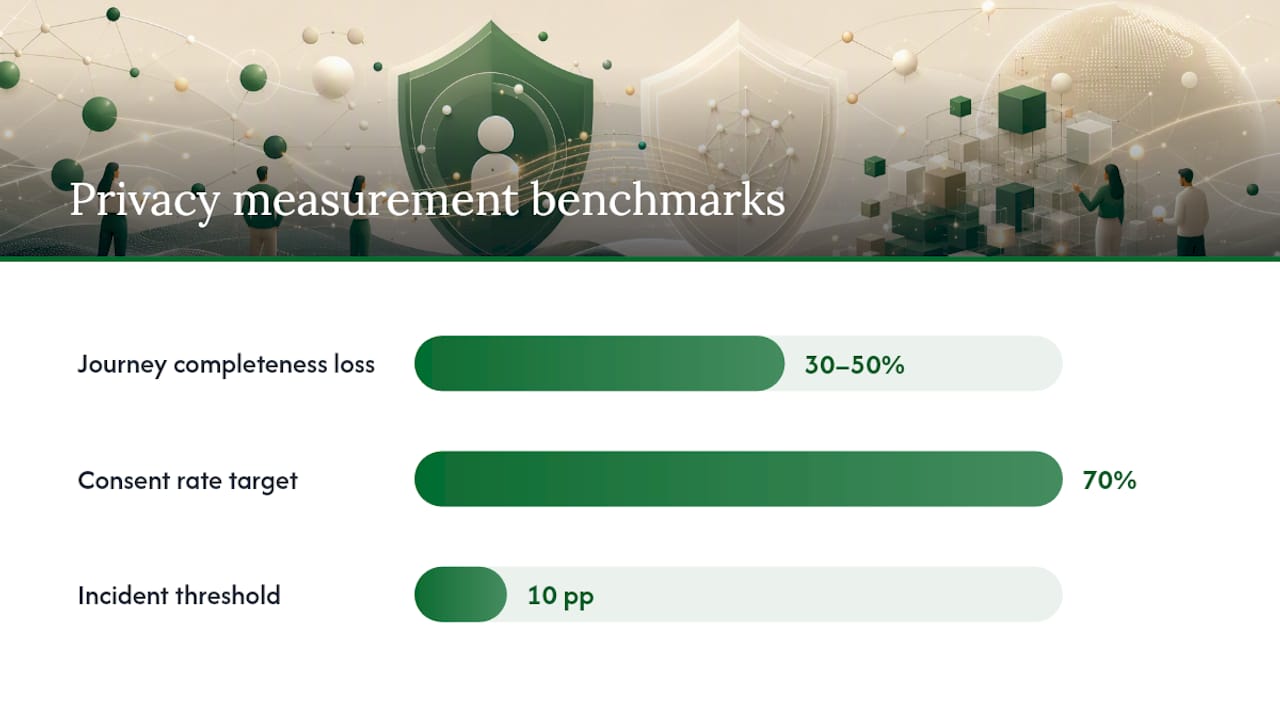
Industry analysis suggests that user-level journey completeness can drop 30–50% in privacy-impacted contexts, creating systematic missingness that biases MTA toward the touchpoints that are still trackable (typically bottom-funnel, logged-in, or consented interactions) and away from upper-funnel exposures.
MMM is structurally more resilient. It uses aggregated spend and outcome data, requires no user identifiers, and doesn’t depend on cookies or device IDs. As privacy restrictions tighten, unified measurement strategies that combine tactical attribution with strategic MMM and periodic lift tests are the emerging best practice.
Practical platform callouts:
- Google Ads: Enhanced conversions and server-side tagging improve signal quality for consented users. Google’s Meridian is designed to work with aggregated data and integrates with Google’s measurement ecosystem.
- Meta: Meta’s Conversion API (CAPI) provides server-side event matching that partially compensates for pixel signal loss. Robyn is Meta’s open-source MMM tool for teams that want to model Meta spend alongside other channels.
- Platform lift tools: Both Google and Meta offer native lift testing products (Brand Lift, Conversion Lift) that can validate MMM and MTA findings without requiring a custom experimentation infrastructure.
Data quality checklist for privacy-resilient measurement:
- Consent capture rate tracked weekly (target: above 70% for MTA reliability)
- Server-side tagging implemented for all key conversion events
- Data lineage documented from raw event to model input
- Missingness rates monitored in MTA identity stitching (what percentage of journeys are incomplete?)
- MMM input tables audited for spend data gaps and outcome metric consistency
Pro Tip: Build a measurement signal quality dashboard that tracks consent rate, identity match rate, and MTA journey completeness week over week. When any metric drops more than 10 percentage points from its baseline, treat it as a measurement incident, not just a data anomaly. Signal degradation that goes unnoticed for months will silently corrupt your optimization decisions.
Analytics investment pays off: research on analytics-driven marketing consistently shows meaningful ROI improvements for teams that build measurement infrastructure before scaling spend, rather than after.
How North Country Consulting combines MTA and MMM for high-spend clients
The following is a representative walkthrough of how a hybrid measurement approach works in practice for a high-spend advertiser.
MTA was their primary measurement tool, but it couldn’t see the CTV or in-store contribution, and their Google Ads branded search campaigns were showing implausibly high ROAS relative to what the business was actually growing.
The approach:
- Consent-first data layer: Audited and rebuilt the consent management setup to capture consent signals at the event level, improving consent capture rate from 54% to 81% within 60 days.
- MTA for consented digital campaigns: Rebuilt the attribution model in Google Ads using data-driven attribution with enhanced conversions, and implemented server-side tagging for Meta. This gave campaign managers reliable signals for Google Ads and Meta optimization decisions.
- MMM weekly for cross-channel budgets: Built a Meridian-based MMM pipeline in BigQuery using 24 months of historical weekly data. The model included CTV spend, in-store revenue (from POS exports), and Google Ads spend as separate inputs. First MMM run showed that CTV was contributing roughly twice what the previous MTA-only view suggested, and that branded paid search had significant overlap with organic brand demand.
- Lift tests for high-stakes reallocations: Before shifting 15% of budget from branded search to Performance Max, ran a 4-week geo holdout test. The test confirmed that branded search had lower incremental lift than the attributed ROAS suggested, validating the reallocation.
What clients should expect from a hybrid measurement engagement:
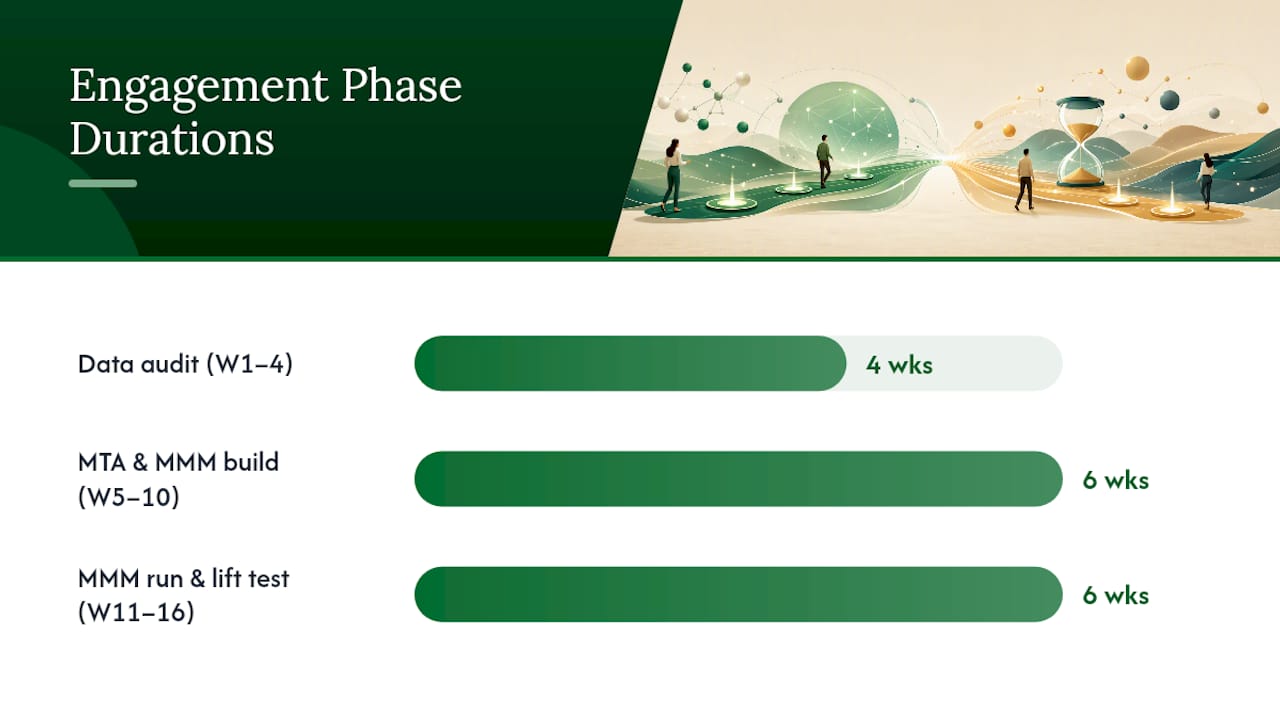
- Weeks 1–4: Data audit, consent infrastructure review, spend schema alignment
- Weeks 5–10: MTA rebuild and MMM data pipeline construction
- Weeks 11–16: First MMM run, cross-validation against MTA, initial lift test design
- Ongoing: Monthly MMM refresh, quarterly lift tests, weekly MTA monitoring
North Country Consulting manages over $40 million in ad spend with an average return on ad spend of 8.7×. The measurement infrastructure described above, consent-first capture, MTA for campaign signals, MMM for budget governance, and lift tests for causal validation, is the framework behind those results.
For measuring success beyond platform-reported ROAS, aligning MER (marketing efficiency ratio) as the MMM outcome metric often produces more stable and actionable budget guidance than optimizing toward platform-attributed ROAS alone.
The future of marketing measurement: a practitioner’s view
The debate between MTA and MMM is mostly settled at the strategic level: you need both, and you need incrementality testing to validate either. What’s less settled is the organizational will to actually build and maintain the infrastructure.
The real risk isn’t choosing the wrong model. Meanwhile, budget decisions are being made on outputs that no longer reflect reality.
Privacy-first hybridization isn’t a trend. It’s the only measurement architecture that will still be functioning in three years. The teams that invest in consent infrastructure, server-side tagging, and a basic MMM pipeline now will have a durable measurement advantage over teams still arguing about last-click vs. linear attribution. Prioritize causality, build governance around your models, and run lift tests on the decisions that actually matter. The minute attribution tweaks are a distraction.
North Country Consulting’s measurement audit for high-spend advertisers
If your attribution setup is producing numbers that don’t match your actual business growth, the problem is almost certainly in the measurement infrastructure, not the media strategy.
North Country Consulting offers a free Google Ads audit that includes a measurement review: consent capture rate, attribution model configuration, conversion deduplication, and a gap analysis against what a hybrid MTA + MMM stack would require. For qualified advertisers spending $25K/month or more on Google Ads, the audit identifies specific revenue leakage from poor measurement and account management practices, with a clear remediation plan.
Engagements typically deliver data contracts, MMM cadence setup, MTA model tuning, and lift test execution within a 16-week timeline. The senior-led management approach means every recommendation comes from practitioners who have built and run these measurement stacks, not account coordinators following a playbook.
Request your audit at Northcountrygrowth.
Sources
The following sources informed the analysis and recommendations in this guide:
- Marketing Analytics: Attribution Is Not Incrementality – Occam’s Razor by Avinash Kaushik
- Multi-Touch Attribution vs Media Mix Modeling — Formula Blog